- Article

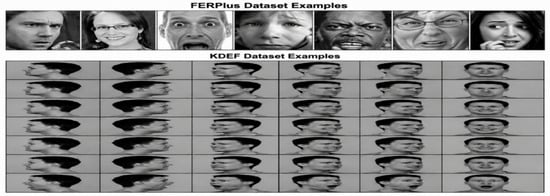
Facial expression recognition remains challenging because subtle expression-related deformations are often obscured by variations in identity, pose, illumination, and class imbalance. This study proposes a hybrid framework that combines an explicit Ridge–Valley Polarity (RVP) image-processing representation with a deep network specifically designed for signed structural inputs. The RVP pipeline applies robust local normalization, multiscale scale-normalized Hessian analysis, curvature-strength and anisotropy weighting, cross-scale sign persistence, confidence estimation, and sign-preserving compression to generate a bounded single-channel map in which positive and negative responses represent ridge and valley tendencies. A polarity-aware encoder subsequently processes this representation through a sign-aware multiscale stem, directional Polarity–Structure Attention Blocks, channel–spatial attention, and complementary attentive-statistics and global-maximum pooling. The framework was evaluated using a subject-independent seven-class KDEF protocol, a seven-class FERPlus protocol, and a five-class FERPlus protocol excluding the severely underrepresented fear and disgust categories. RVP consistently outperformed raw grayscale input across accuracy, macro-precision, macro-recall, and Macro-F1. The proposed model achieved 84.01% accuracy and 83.48% Macro-F1 on KDEF, 81.50% accuracy and 69.83% Macro-F1 on seven-class FER, and 84.37% accuracy and 82.04% Macro-F1 on five-class FERPlus. RVP also increased mean pairwise Mahalanobis class separability on both datasets. End-to-end latency was 11.506 ms/image for KDEF and 10.798 ms/image for FERPlus, corresponding to throughputs of 86.91 and 92.61 images/s, respectively.
14 November 2026